Azure Fabric :: Part 6 — Semantic Layer, AI/ML and Optimization
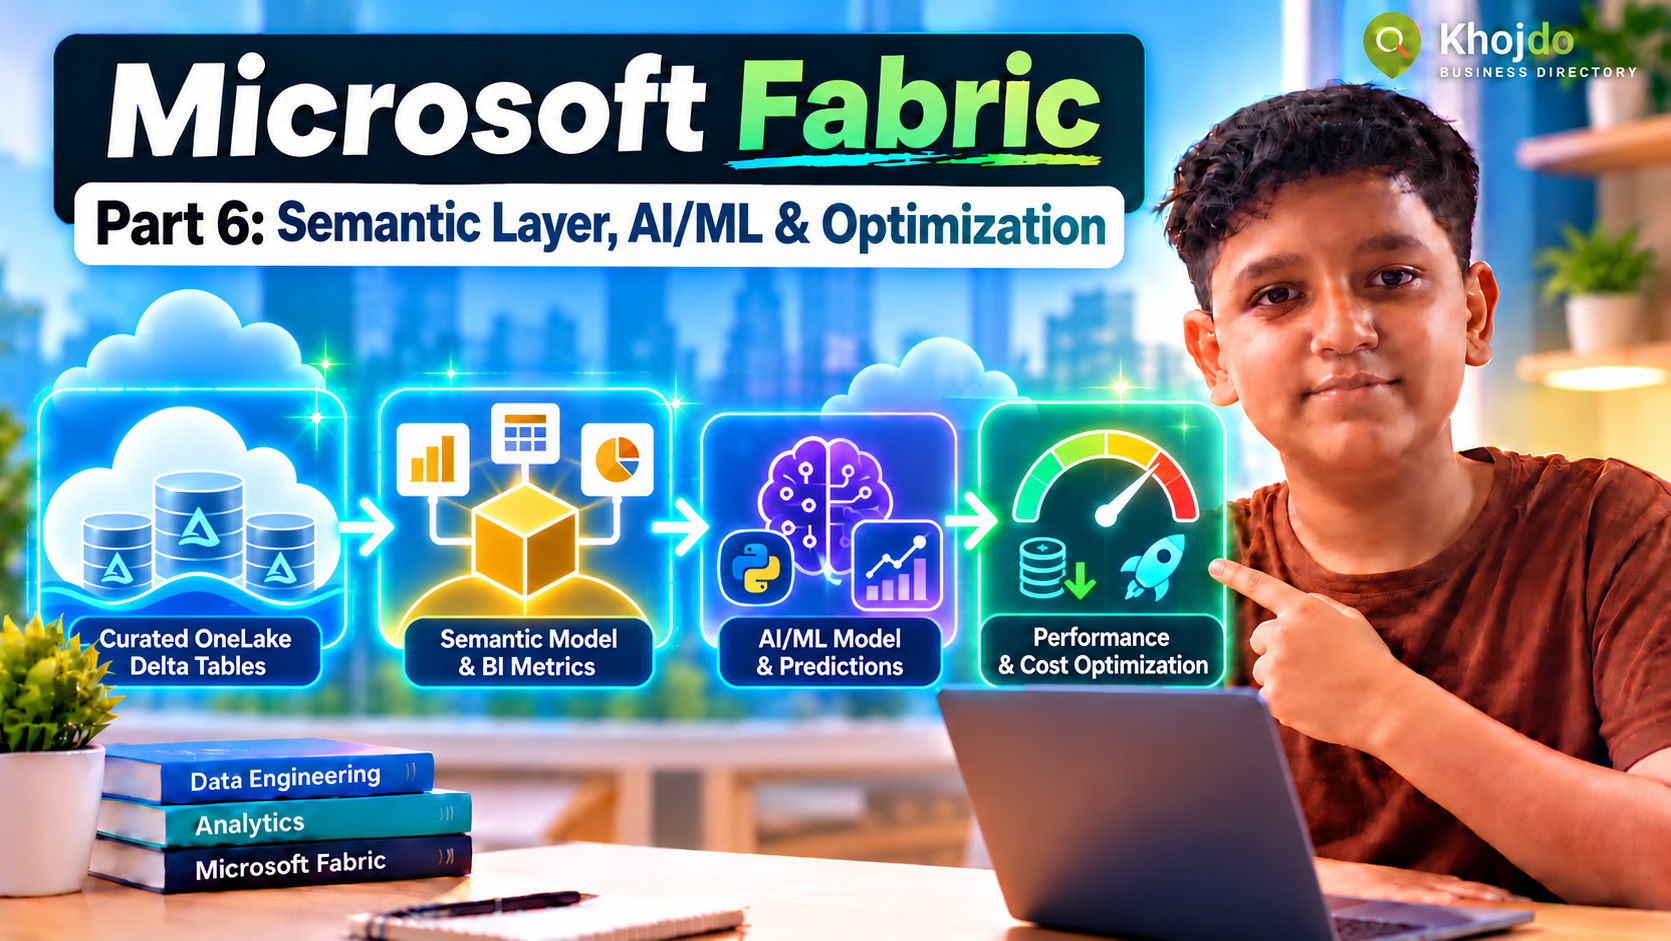
Build a trusted Direct Lake semantic model, prepare governed data for AI/ML, and optimize query performance, Delta tables, capacity and cost.
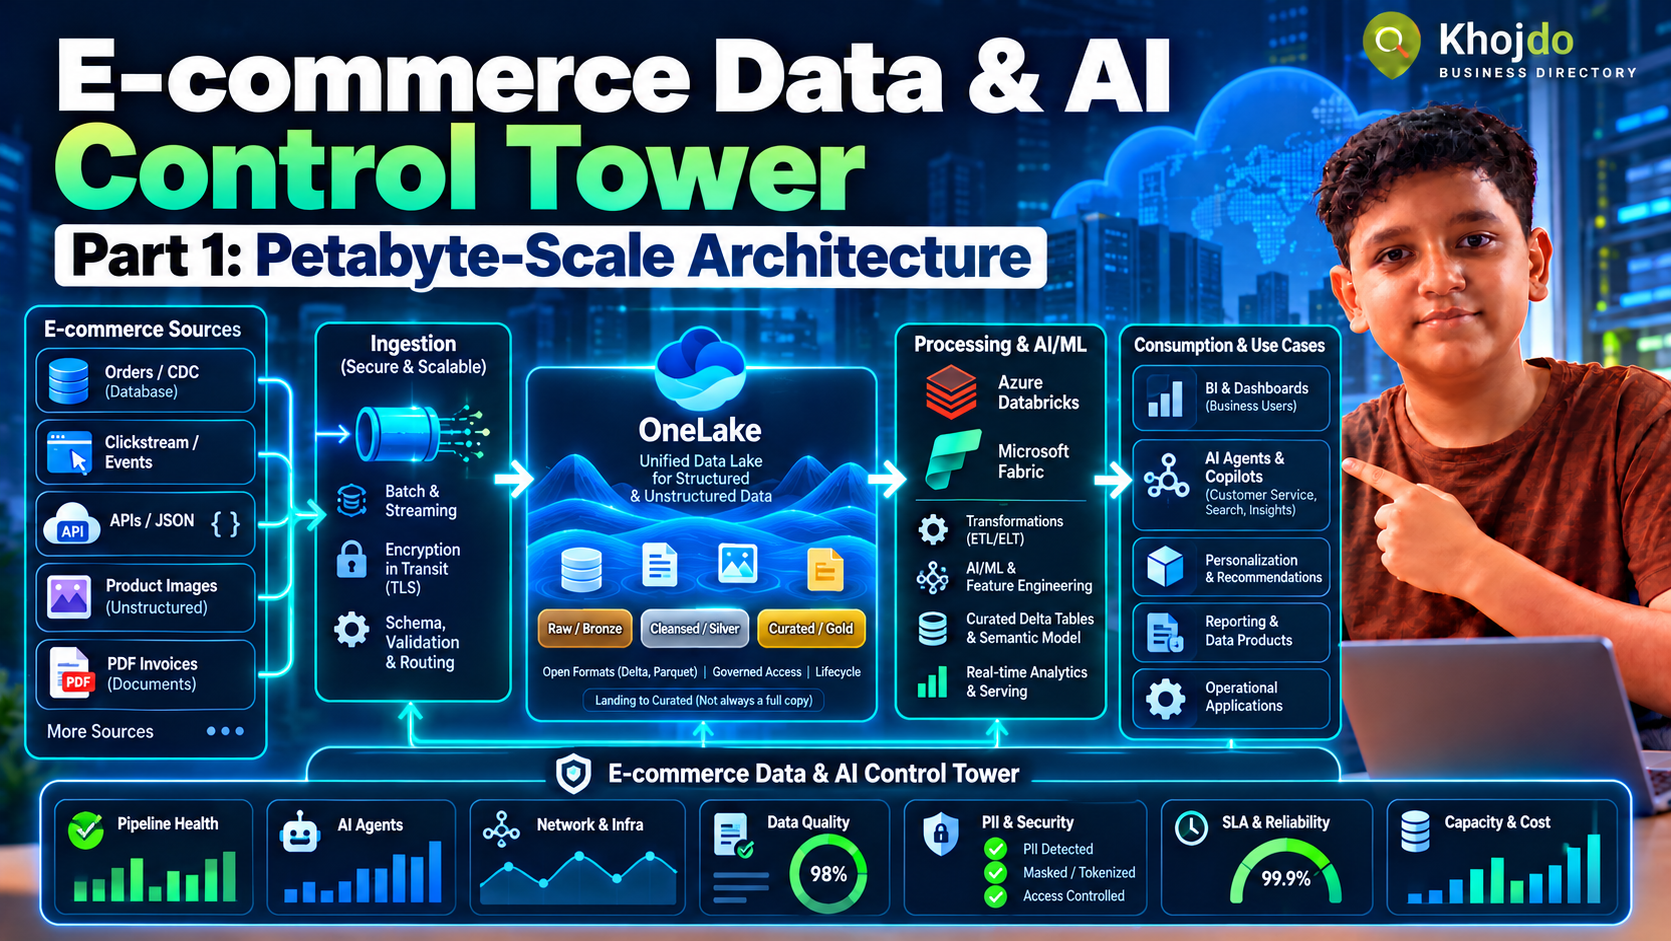
Parts 1–5 built a practical data path from ingestion through transformation, governance and deployment. This final part adds the consumer and intelligence layers: a semantic model for shared business definitions, an AI/ML workflow for predictions, and a measured optimization loop for performance, capacity and cost.
Architecture: from trusted tables to decisions
Curated OneLake Delta tables → semantic model and business measures → reports and decisions. Alongside that path, validated feature tables can feed experiments and batch scoring; predictions return to OneLake as a governed table for reporting or downstream applications.
Part A — Create a semantic model on curated data
- Open the Fabric workspace and select the Lakehouse or Warehouse containing the curated Gold tables from Part 4.
- Choose New semantic model (or create one from the OneLake catalog) and select the fact and dimension tables needed for a defined reporting use case. Name it clearly, for example
Sales_Analytics_Model. - Open the model. Confirm the fact table grain, such as one row per order line. Relate dimensions such as Date, Product and Store to the fact using unique dimension keys and one-to-many relationships.
- Use clear business-friendly names. Hide technical keys and fields report authors do not need. Add descriptions to measures and tables.
- Create explicit measures for shared business definitions. For example, define Net Sales consistently rather than allowing each report to calculate it differently.
- Set a date table and useful hierarchies where they improve analysis. Add row-level security only when required, test each role with representative users, and confirm permissions at both model and workspace level.
- Build a small report and validate its totals against a known query or finance-approved sample. Check that filters and date selections behave as expected.
A star schema is a strong starting point: dimensions filter and group results; fact tables store measurements at a declared grain. Avoid loading every raw column into the model. Create a semantic model explicitly from the Lakehouse or OneLake catalog.
Microsoft illustrated steps: create and edit a Direct Lake semantic model in the Fabric web experience · Star schema modeling guidance for Power BI semantic modelsPart B — Prepare a responsible AI/ML data layer
- Start with a business decision, not an algorithm. State who will use the prediction, what action it supports, how often it is needed and what a useful improvement would look like.
- Create a training table from curated, permissioned data. Define the target label, observation window, prediction time and eligible population. Keep identifiers needed for joins separate from model features.
- Prevent data leakage: a feature must be available at the time the prediction would have been made. For time-based use cases, split training, validation and test data chronologically.
- Check missing values, duplicates, label quality, outliers and representation across relevant groups. Remove or protect personal data that is not needed for the use case.
- In the Fabric workspace, create a notebook and a Machine Learning Experiment. Train a simple baseline model first; log parameters, metrics and run details so results can be compared.
- Compare the baseline with candidate models using business-relevant metrics, not accuracy alone. Review false positives and negatives, subgroup performance, explainability and operational constraints with the data owner.
- When a run meets acceptance criteria, save it as a Machine Learning Model. Use Fabric’s supported batch-scoring workflow or notebook scoring to produce predictions.
- Write predictions, model version, scoring timestamp and input batch/run ID to a separate Delta table, for example
gold_sales_predictions. Validate counts, null rates and prediction ranges before sharing results. - Monitor input freshness, feature drift, prediction distributions and realized outcomes. Define a retraining/review trigger with the business owner; do not retrain automatically without validation and approval.
Part C — Optimize performance and cost using evidence
- Set a baseline: record report response time, data freshness, pipeline/job duration, failed-run rate, capacity consumption and storage growth for a representative period.
- Find the bottleneck: use Power BI Performance Analyzer for slow visuals and the Fabric Capacity Metrics app to identify high-consumption items, busy time windows and throttling.
- Improve the semantic model: use a clear star schema, remove unused high-cardinality columns, use explicit measures, avoid unnecessary bidirectional relationships, and test Direct Lake behavior against the security and source features in use.
- Maintain Delta tables: inspect small-file growth and use Lakehouse table maintenance to compact files when measurements show a benefit. Schedule maintenance to avoid competing with peak loads.
- Choose layout optimizations deliberately: V-order can help read-heavy reporting but may increase write time. Use clustering or Z-Order only for columns that appear in selective filters and only after benchmarking. Avoid partitioning small tables or creating many tiny partitions.
- Right-size the work: reduce unnecessary full refreshes, limit data to the reporting/ML need, stagger heavy jobs, and use incremental processing where correctness allows.
- Re-measure after each change: compare latency, CU consumption, storage, reliability and business value against the baseline. Keep the change only if it improves the agreed outcome without breaking the SLA.
Define ROI and SLA measures
- Freshness SLA: maximum permitted delay from source arrival to the report or prediction being available.
- Reliability SLA: successful run percentage, recovery time, retry policy and named support owner.
- Performance SLA: agreed response-time target for key reports or scoring jobs, measured with representative workload.
- Cost/ROI: capacity units or cost per refresh/scoring batch, storage growth, manual effort saved, and business outcome attributable to the solution.
- AI/ML value: measure incremental lift against a baseline and monitor false-positive/negative impact, review burden and drift—not just model accuracy.
Common mistakes and mitigation
- Building a semantic model directly on raw ingestion tables: model curated, quality-checked tables with an agreed grain and business definitions.
- Different reports defining the same KPI differently: centralize important calculations as reviewed semantic measures and document their owner.
- Training on future information: use point-in-time features and chronological evaluation to prevent leakage.
- Calling a model production-ready after one good metric: compare with a baseline, review group-level errors, validate operations and obtain business approval.
- Optimizing from intuition: capture a baseline and use query/capacity evidence before changing model design, table layout or capacity.
- Applying V-order, clustering or partitions everywhere: benchmark representative reads and writes; choose only the layout changes that improve measured workloads.
- Leaving model output ungoverned: store model version, scoring time, data lineage, owner, permissions and retention with prediction tables.
Part 6 completion checklist
- A Direct Lake semantic model uses curated fact and dimension tables with documented measures.
- A report reconciles to a trusted total and model access has been tested.
- An ML experiment records a baseline, evaluation metrics and model version.
- Batch predictions are written to a governed Delta table and checked before use.
- Performance and cost have a baseline, owner and review cadence.
This completes the beginner path: ingest → unify → transform → govern → deploy → model and optimize. For a production rollout, involve platform, security, data governance and business owners before connecting real systems or enabling automated decisions.