Azure Fabric :: Part 1 - Planning companion before Part 2
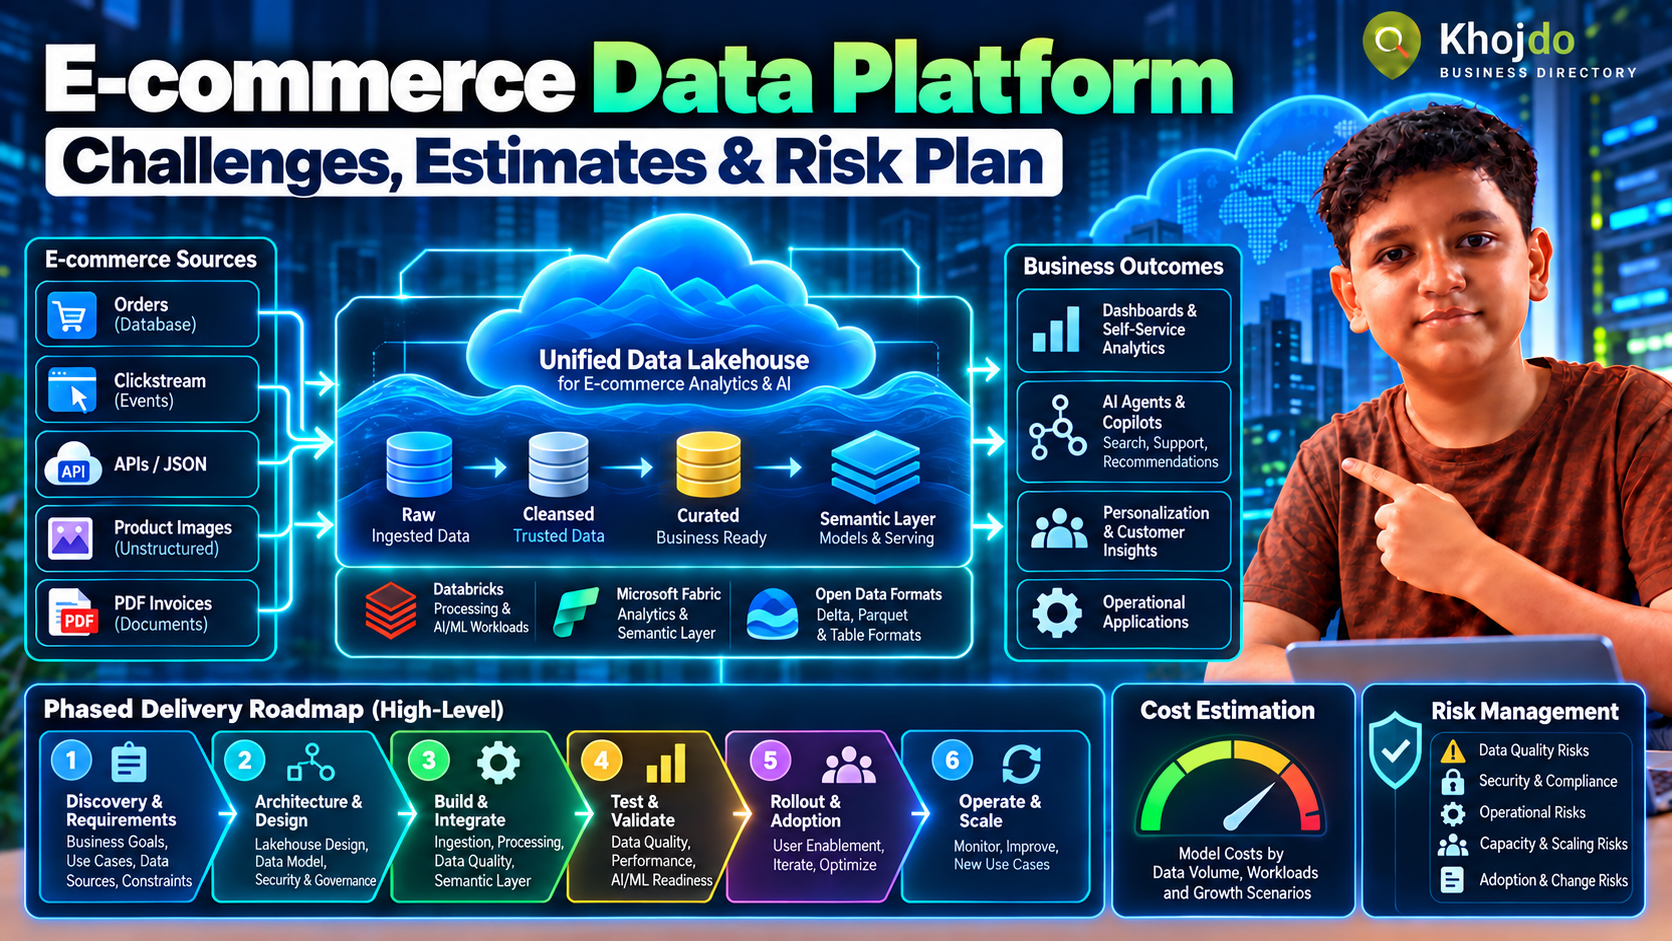
A phased effort and cost-planning baseline for a petabyte-scale e-commerce platform using Fabric and Databricks, including major risks and mitigations.
Planning companion to the Fabric and Databricks Control Tower series
Architecture and roadmap are illustrative. Effort and cloud-cost levels below are planning ranges, not a fixed quote or SLA.Before Part 2 designs the ingestion pipelines, this article lays out the delivery risks, rough effort and cost model for an expert-level e-commerce Data & AI platform on Microsoft Fabric and Azure Databricks. The target includes petabyte-scale history, high daily change volume, databases and CDC, events, APIs, JSON, images, PDFs, PII controls, complex downstream processing and a unified operational Control Tower.
Planning assumptions
These are example planning assumptions to make the estimate concrete, not facts about a specific company: approximately 1–3 PB of historical data, 5–20 TB/day of changing data across all feeds, 15–25 source systems, separate Development/Test/Production environments, and a primary region with a separately planned recovery strategy. Actual scope depends on source count, file-size distribution, network path, retention, required freshness, legal/privacy controls and agreed SLA.
Unlock this series to read the rest
This article belongs to a set. One payment opens every part for the period shown.
Already bought it? Sign in with the email you paid with, or open your access link.