Choosing and Connecting Data Engines
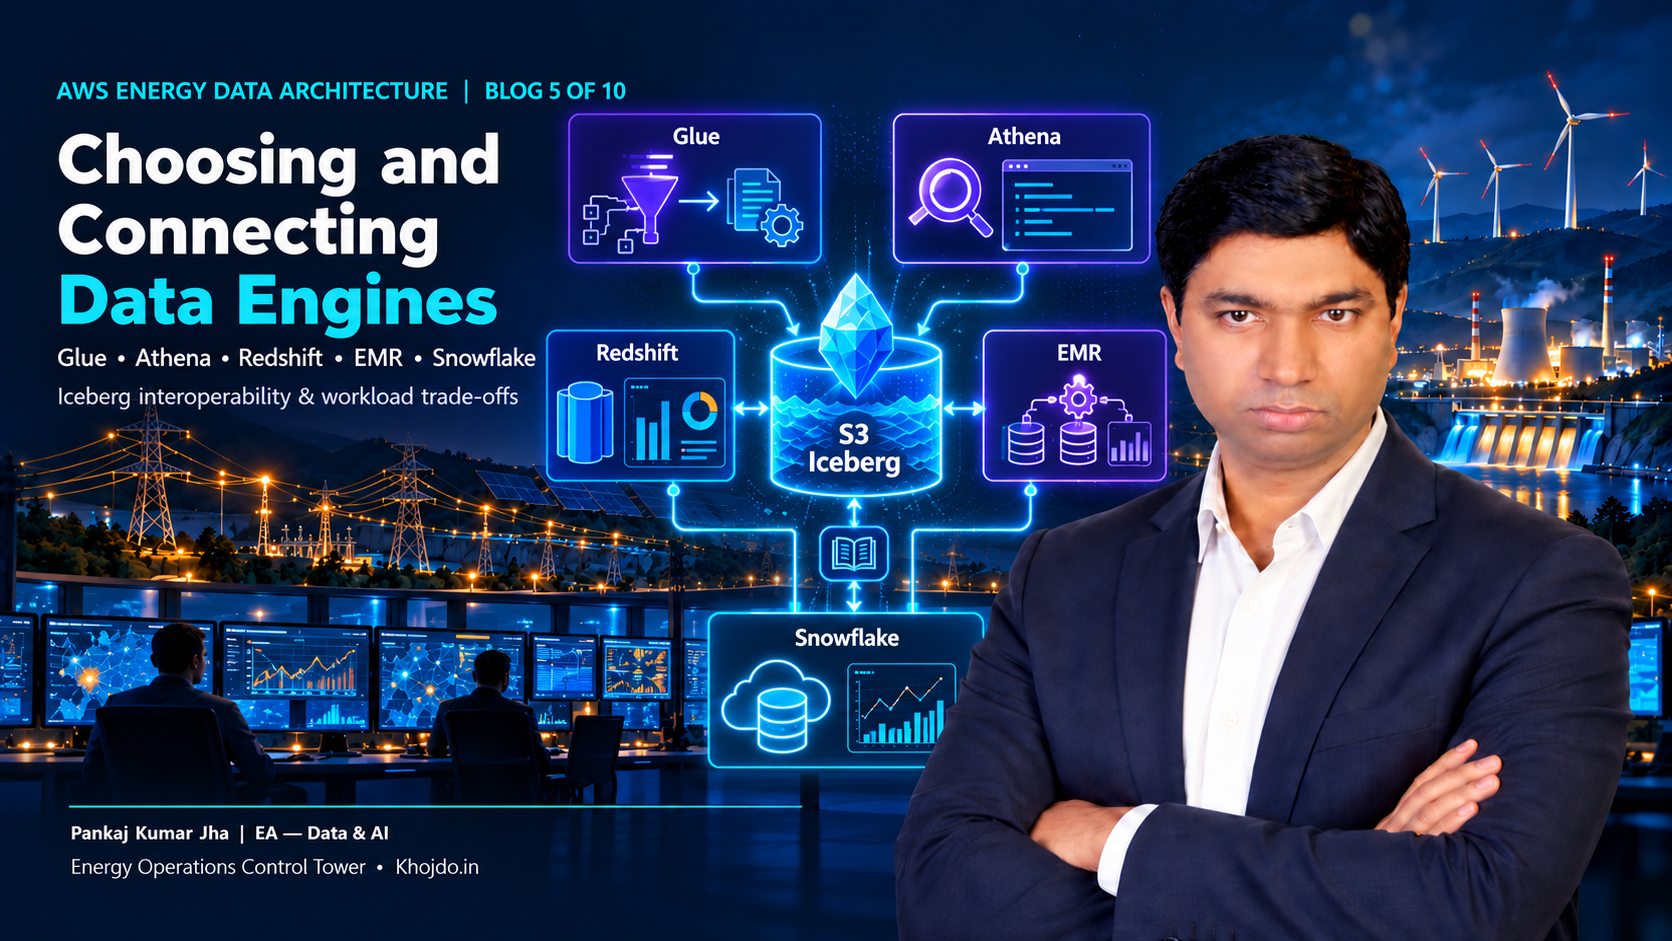
A workload-based guide to choosing AWS Glue, Athena, Redshift, EMR or Snowflake for the energy operations control tower, including Iceberg interoperability, cost and operating trade-offs.
AWS Energy Data Architecture | Blog 5 of 10
Choosing and Connecting Data Engines: Glue, Athena, Redshift, EMR and SnowflakeBy Pankaj Kumar Jha | EA — Data & AI
Choose compute for the workload; govern data and table access consistently.Scenario: An energy company is building a control tower over generation, smart-meter, asset, weather and market data. The platform already uses Amazon S3 and Apache Iceberg for shared data products. Different teams need transformation, exploration, operational dashboards and large-scale processing. The architecture team must choose the right engine for each job without creating unnecessary copies or an unmanageable mix of platforms.
Architect’s principle: Choose the engine from the workload’s access pattern, performance target, skills, cost model and operating constraints. Iceberg can help multiple engines work with shared table data, but it does not make their features, permissions, performance or operational behavior identical.
Create a free account to read the rest
This article is open to registered readers. Signing up takes a minute and costs nothing.